01 of 202026
UnTune
Strips the music out of any video, live, and keeps the voices.
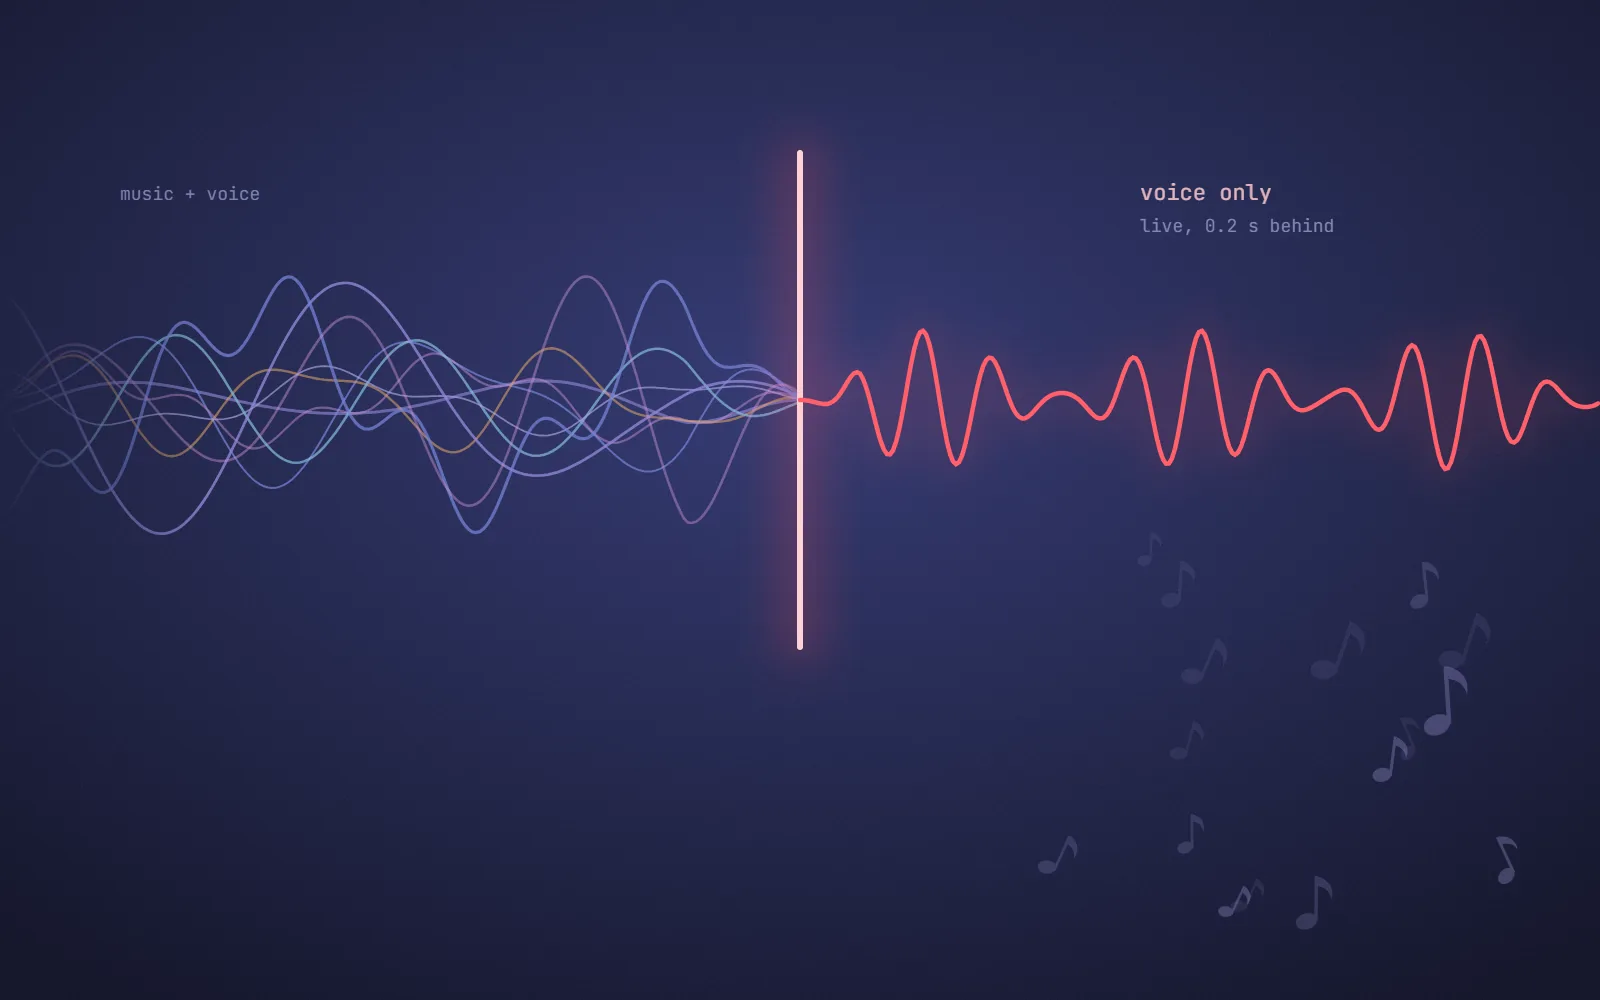
- 0.2send-to-end latency in live mode
- 8sto clean a one-minute clip
- 1,000+test passes
- 300+people at the showcase demo
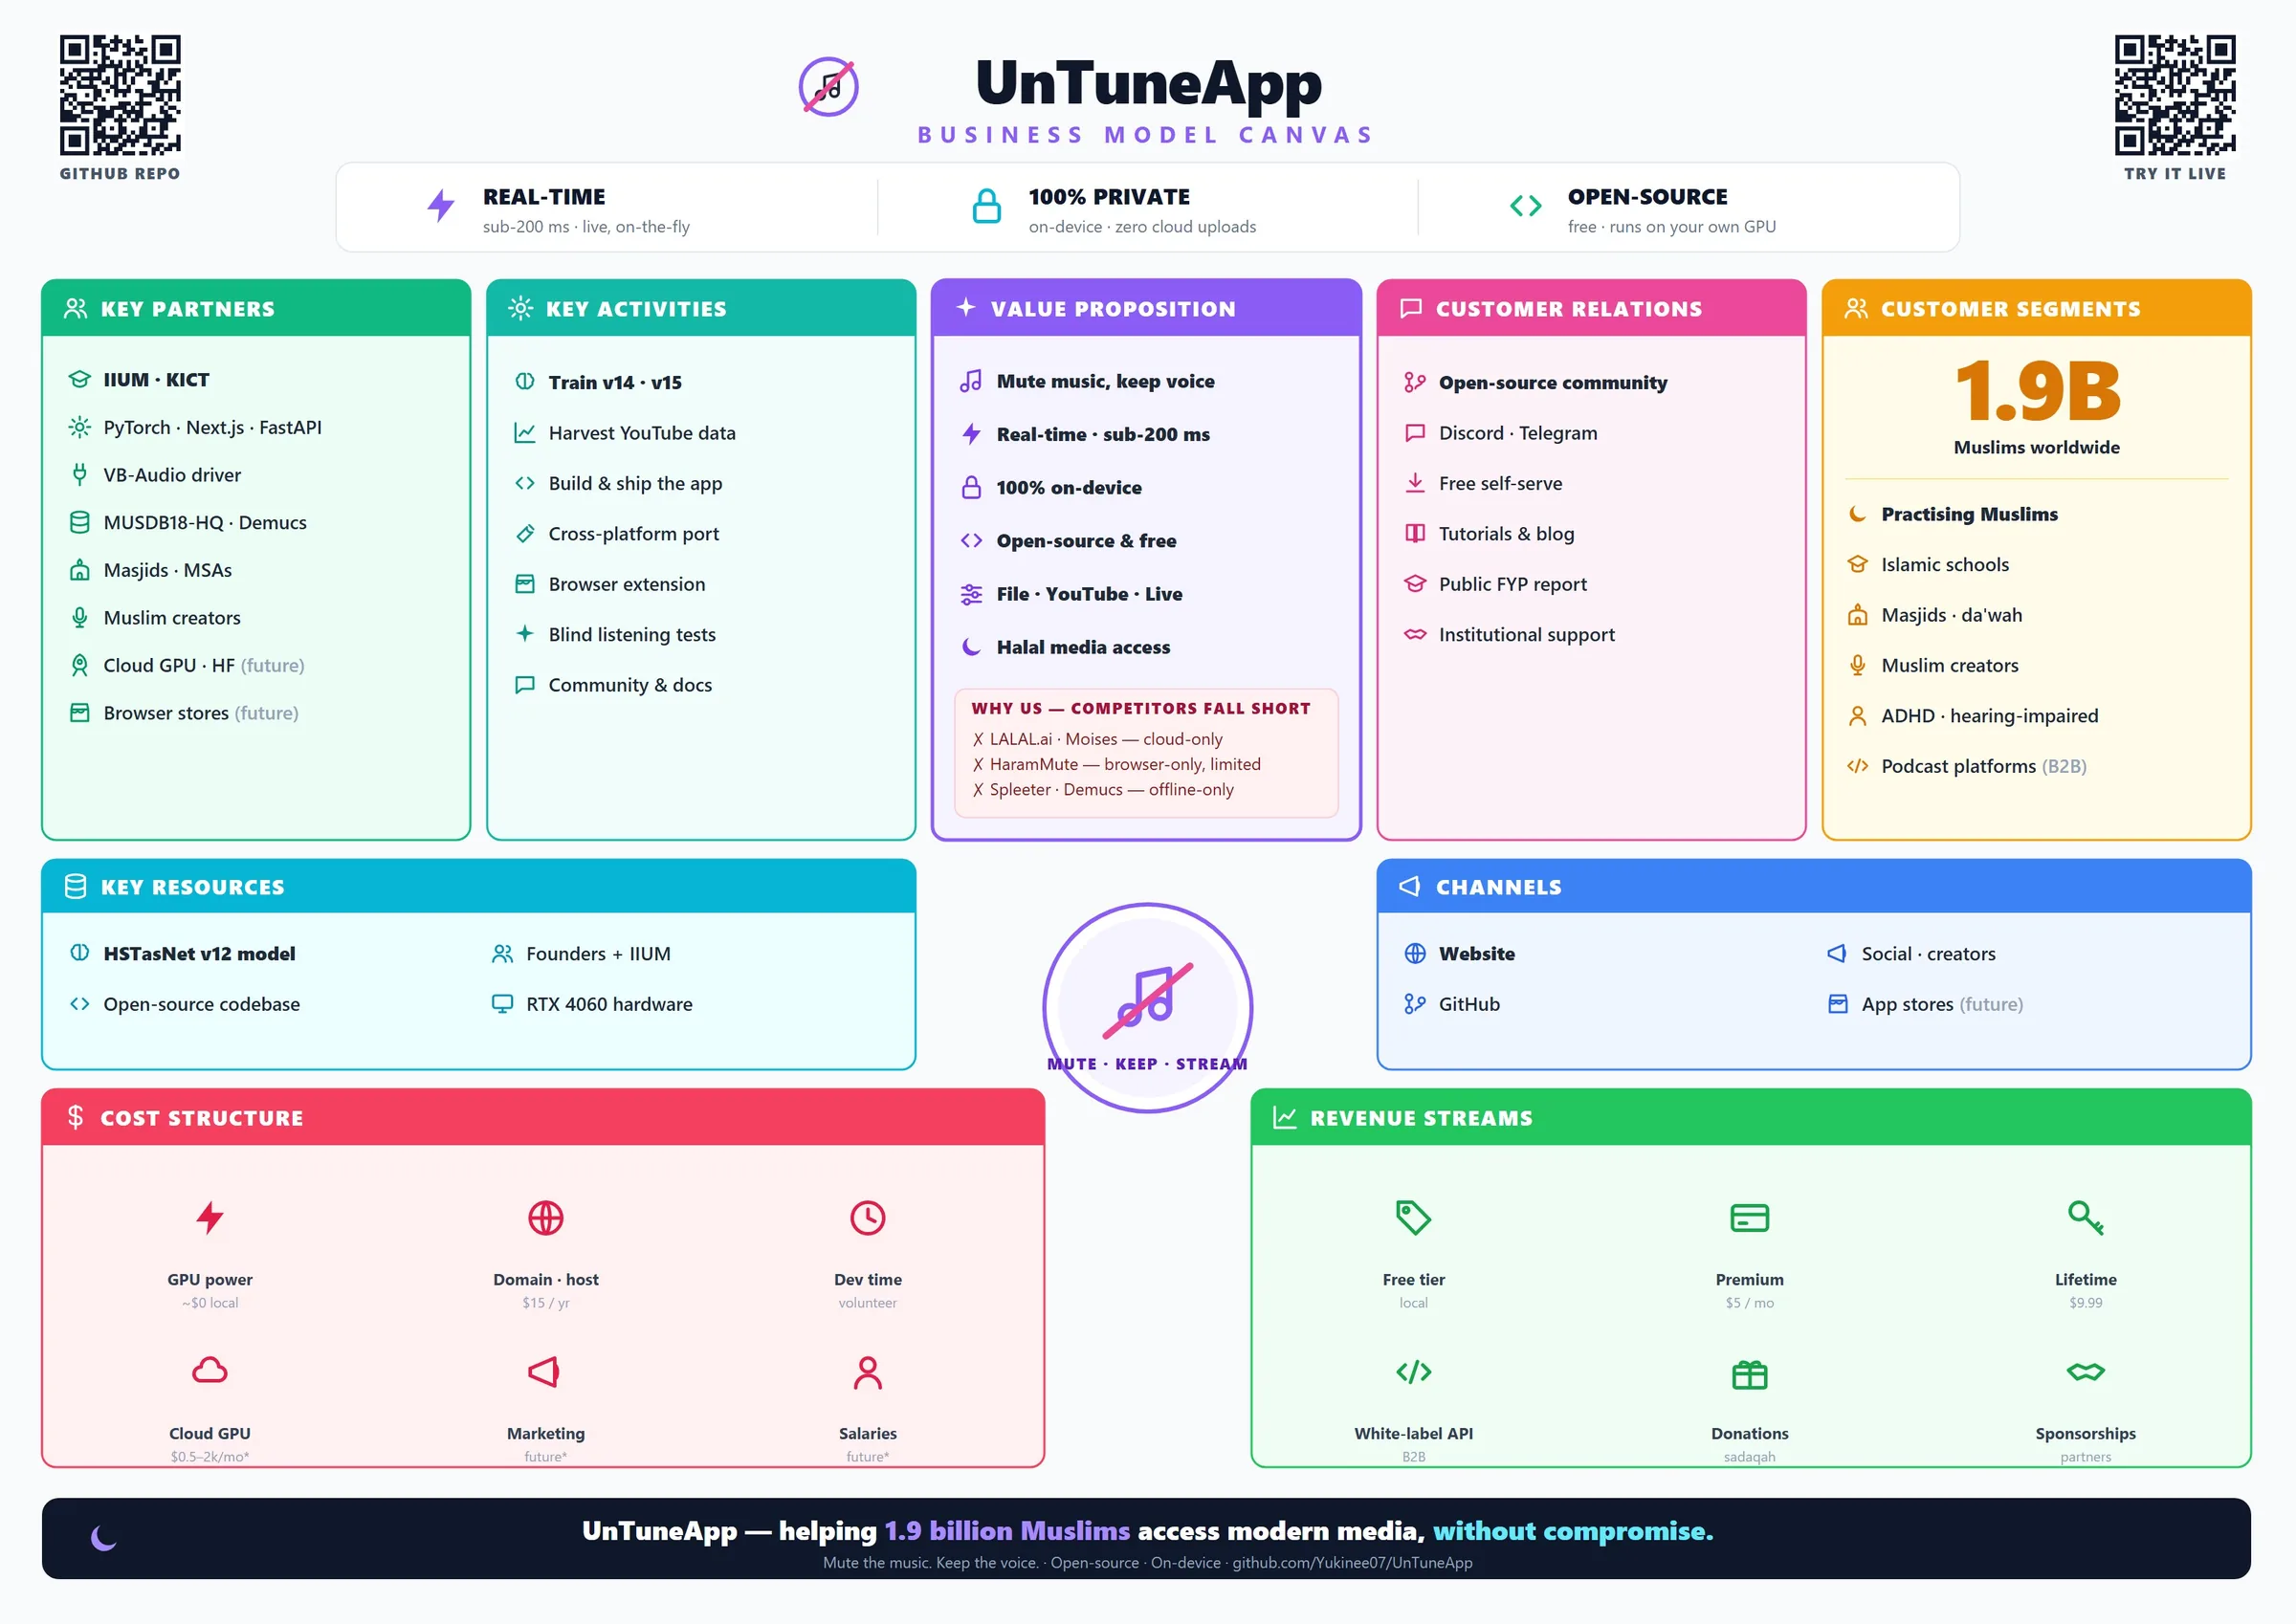
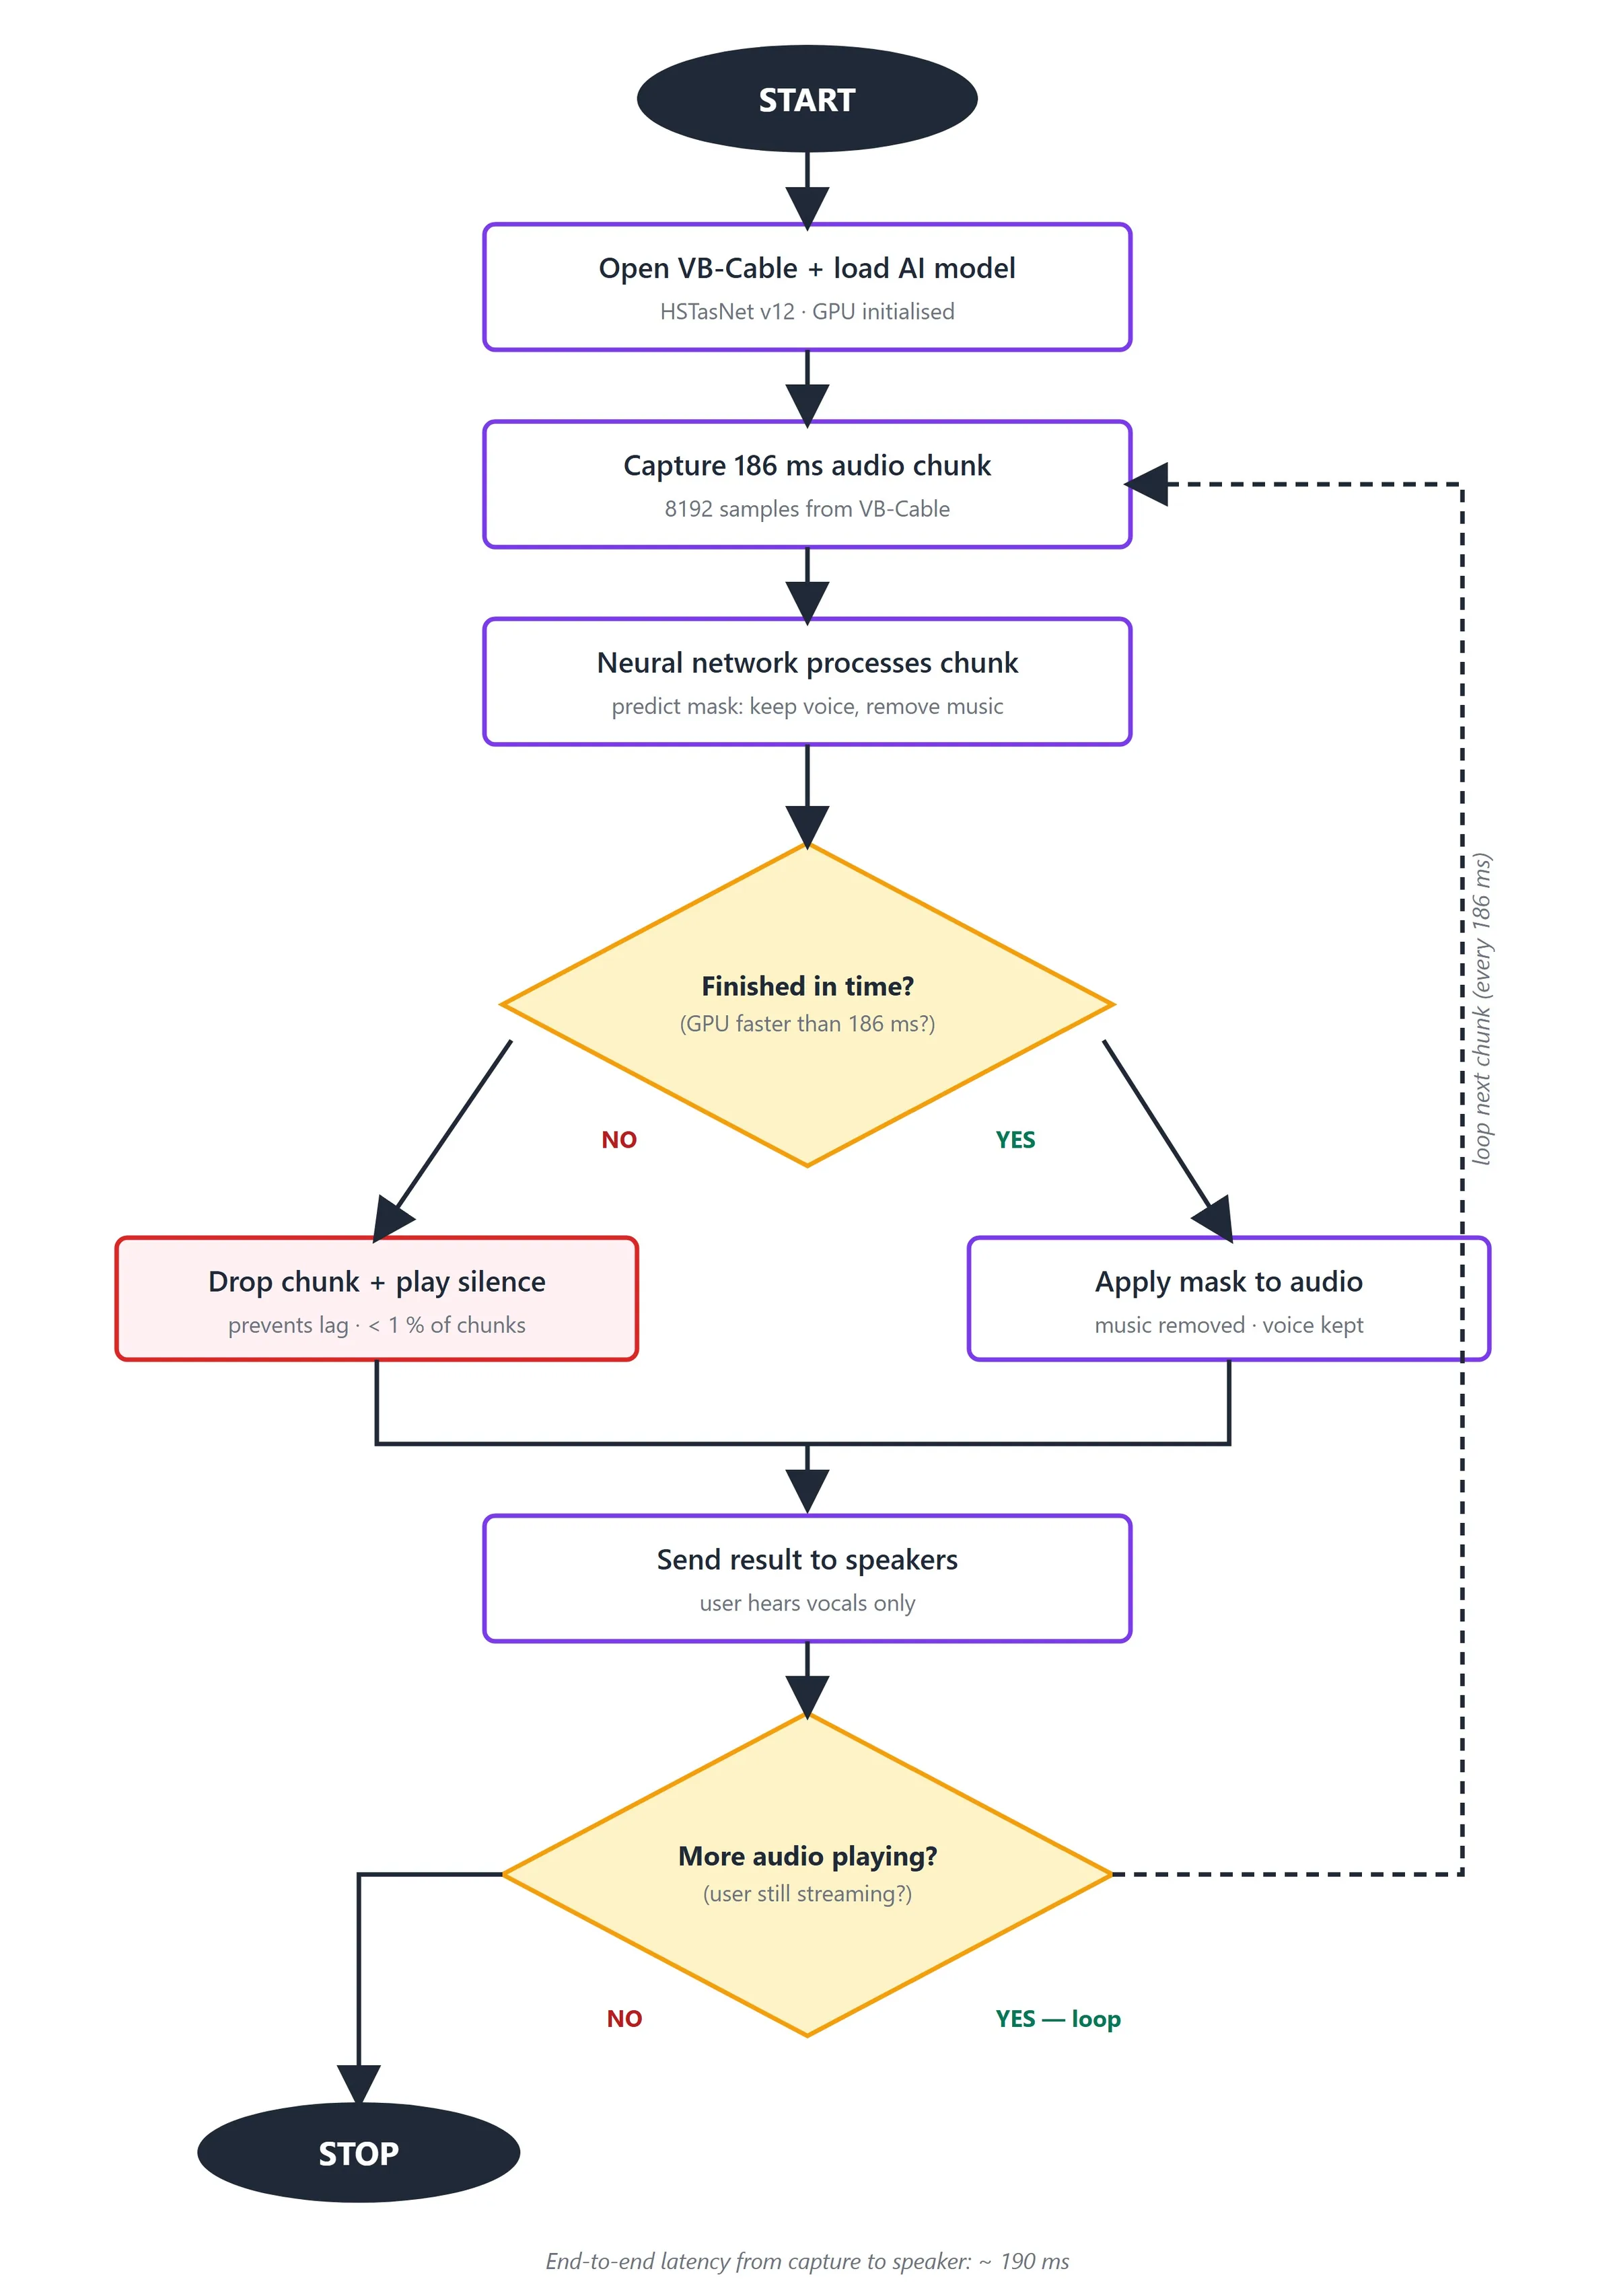
People who avoid music still want to watch lectures, reels and the news. UnTune listens to the audio, separates voice from music with a deep learning model, and plays back only the voice, fast enough to use while you scroll.
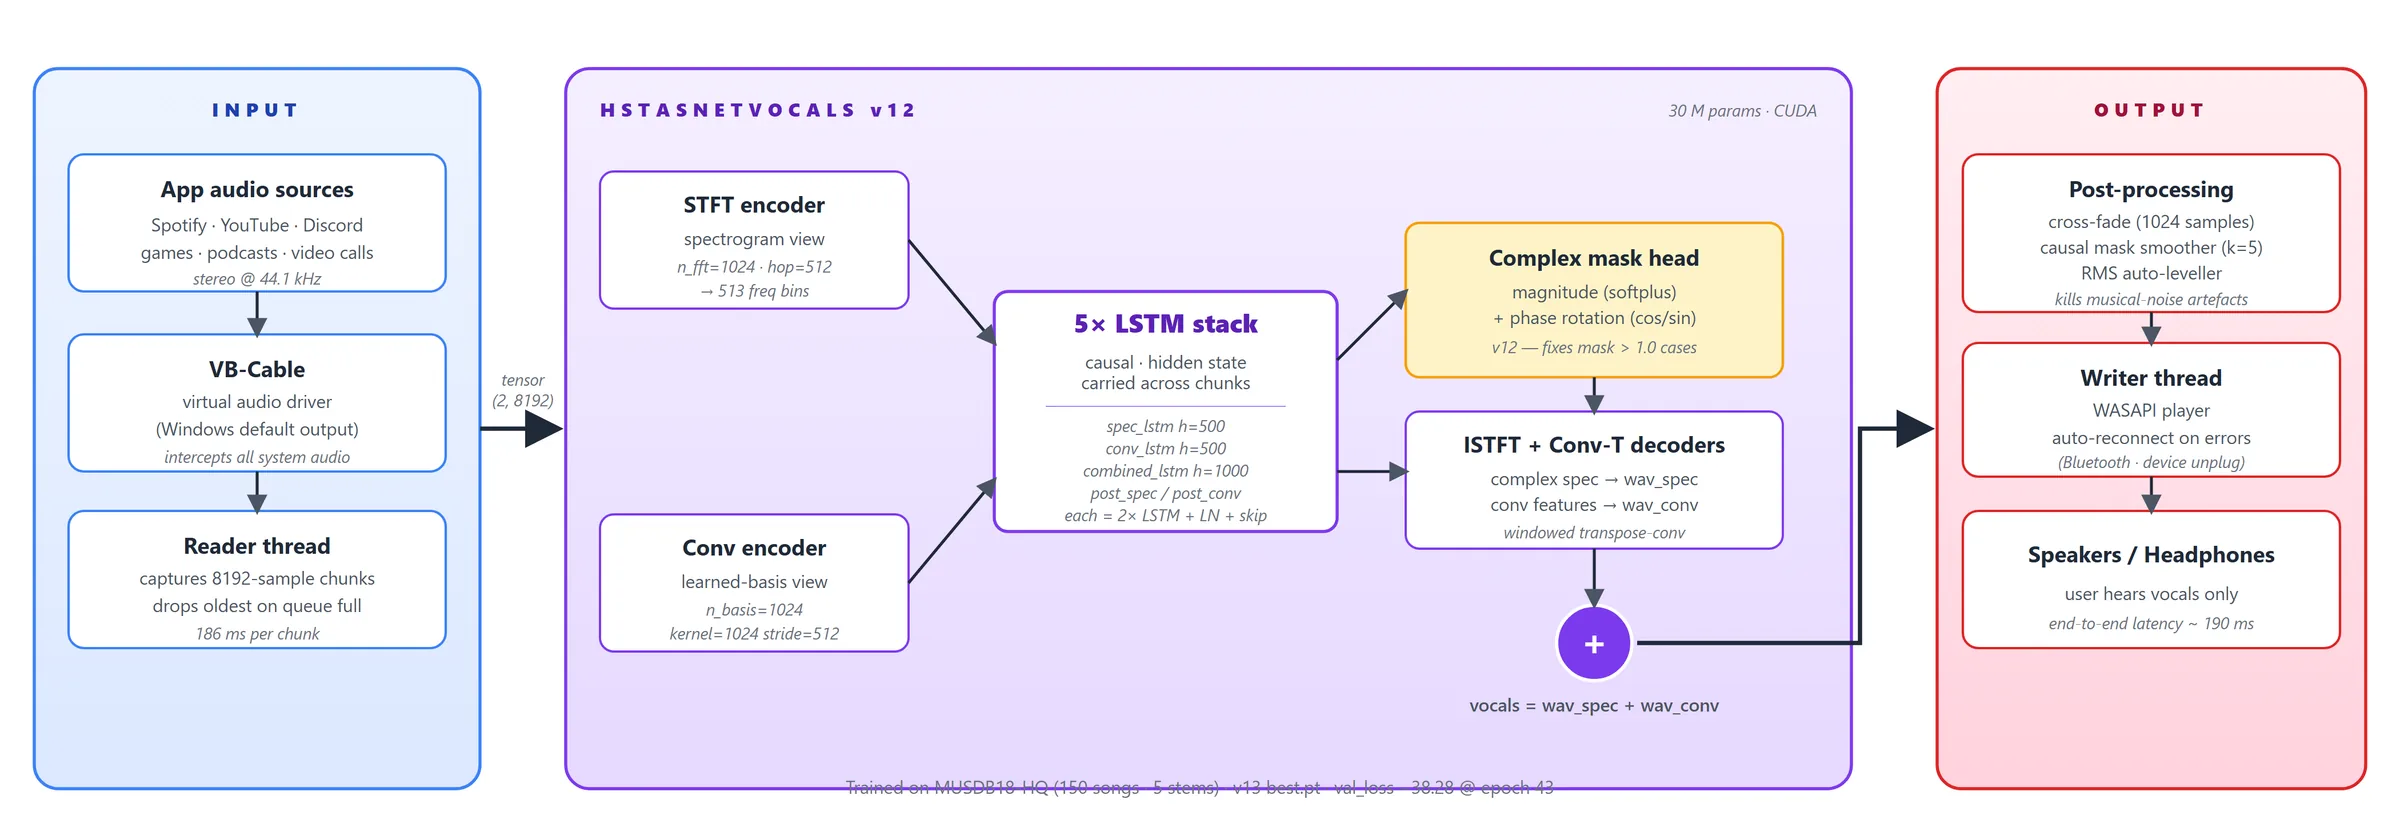
I retrained and tuned an HSTasNet-based separation model over 20+ runs of one to three days each, then ran more than 1,000 test passes on clips from a few seconds to several hours long. Piano is the last hard case: its spectrum sits closest to the human voice.
It runs as three pieces: a Next.js frontend with five clear job states, a FastAPI backend with an async job queue, and a dedicated Python process that routes live system audio through the GPU.
Hear it Real output, nothing simulated
Drag the music away. The voice stays.

 Voice onlyOriginal
- Model
- V15, the 5.2 M parameter model that runs in real time
- Music in the pauses
- 20 dB quieter
- Voice accuracy on this clip (uSDR)
- -1.3 dB to 6.9 dB
Narration by the team, over music generated for our StokLah promo, so the clean voice is known and the score can be measured. Generated music is an easy test. On 30 held-out speech-over-music clips with real songs, the averages were 9.88 dB live and 14.93 dB with the best model.